Skip to content

Open to remote and Dallas–Fort Worth opportunities

GenAI / ML Engineer

Armand Junior Dongmo Notue: I build AI systems that go beyond prototypes.

I engineer LLM applications, autonomous agents, retrieval systems, and machine learning solutions — with a focus on evaluation, reliability, and real-world deployment.

  • Based in Dallas–Fort Worth, TX
  • Open to remote opportunities
  • U.S. Permanent Resident
  • GenAI Engineer
  • LLM Engineer
  • ML Engineer
  • AI Engineer
  • Data Scientist

●  How I build AI systems

Agents—Orchestration with explicit state

Planners, parallel workers and tools wired as a graph with typed state, token budgets and bounded loops.

A general shape for production AI systems, not the architecture of a single project. Select a stage to see where it shows up in my work.

What I bring to a team

  • Ships real AI products

    IntelliCast is live in early access — an agent cycle, cross-outlet claim checks and voice, deployed on AWS with CI.

    See IntelliCast
  • Builds agentic systems, not demos

    Atlas runs parallel LangGraph researchers, a critic grounded in retrieved sources and an enforced token budget — with measured latency.

    See Atlas
  • Knows how LLMs are evaluated

    Nearly two years of LLM post-training work: RLHF preference ranking, fine-tuning examples, and red-teaming for hallucinations and jailbreaks.

    See experience
  • Rigorous with data

    Caught a leakage bug behind a perfect score, reports effect sizes next to p-values, and labels modeled numbers as modeled.

    See the churn study

01Featured projects

Systems I've designed, built and measured.

Independent projects with public code or a live product. Results are reported as measured, with the caveats that keep them honest.

All projects
  • 01Live · Early access

    Agentic AI · LLM Applications · Full-Stack AI

    IntelliCast AI — Personal news agent

    A personal news agent that follows the world for you, checks claims across sources, and briefs you by voice.

    Problem
    News products hand people more to read. Following the few stories that matter — and knowing which claims are actually confirmed — still takes time and judgment.
    Approach
    An agent cycle clusters articles into evolving stories, verifies claims across outlets, ranks stories against each listener's goals, and turns the result into a fact-checked, two-host audio briefing you can question.
    outlets on a 30-minute agent cycle
    14
    tap to first audio · internal testing
    ~15 s
    offline backend tests in CI
    180
    • Python
    • FastAPI
    • React
    • TypeScript
    • PostgreSQL
    • pgvector
    • Llama 3.3 70B
    • +5 more
    View case study

    Source is private — happy to walk through the architecture.

    SOURCESSTORIESCLAIMSBRIEFING1HOST AHOST BEN · FRSchematic
  • 02Core complete · Evals in progress

    Agentic AI · LangGraph · Grounded critique

    Atlas — Autonomous multi-agent research platform

    A multi-agent research platform: parallel researchers, a critic grounded in the sources it retrieved, and a live view of the agent graph as it runs.

    Problem
    Single-pass LLM research is slow when sequential and unreliable when unchecked — and a minute-long agent run shouldn't die with the browser connection.
    Approach
    A LangGraph planner fans out parallel researchers; a critic checks the answer against retrieved sources and sends back only the faulty branches; runs execute on a worker and stream to the UI over resumable SSE.
    5 parallel branches · 93.4 s if run back to back
    23.3 s
    submit to first visual feedback
    1.14 s
    backend · frontend tests, no network
    168 · 34
    • LangGraph
    • Claude Sonnet 5
    • GPT-4o (failover)
    • FastAPI
    • arq
    • Redis
    • PostgreSQL
    • +4 more
    PLANRESEARCH × NSYNTHESIZECRITICplannerr1r2r3r4synthesizercriticTARGETED RETRYCITED≤ 2 ROUNDS · TOKEN BUDGET ENFORCEDSchematic
  • 03Complete

    Machine Learning · Deep Learning · Anomaly Detection

    Real-Time Fraud Detection Ensemble

    A stacked ensemble where autoencoder and Isolation Forest anomaly scores feed an XGBoost decision — tuned to catch fraud at a very low false-alarm rate.

    Problem
    Card fraud is rare — under 0.2% of transactions in the benchmark data — so accuracy is meaningless, and every false alarm is friction for a real customer.
    Approach
    An autoencoder trained only on legitimate transactions and an Isolation Forest each produce an anomaly score; XGBoost makes the final call over 44 engineered features plus both scores.
    ROC-AUC
    0.9834
    recall
    85.71%
    false-positive rate
    0.16%
    • Python
    • PyTorch
    • scikit-learn
    • XGBoost
    • pandas
    • NumPy
    TXNS44 FEATURESDETECTORSXGBOOSTP(FRAUD)AUTOENCODERISOLATION FORESTSCALED FEATURESTHRESHOLDSchematic
  • 04Complete

    Recommender Systems · Machine Learning · Evaluation

    Recommendation Engine from Scratch

    Five recommenders built from first principles on 568,454 Amazon reviews, compared with ranking metrics, significance tests and a popularity-bias audit.

    Problem
    Recommender comparisons often stop at a single accuracy number. On extremely sparse data, which method actually ranks best — and at what cost to fairness?
    Approach
    Implemented popularity, user-based CF, SVD, TF-IDF content-based and a hybrid ensemble with NumPy and SciPy, then evaluated with leave-one-out HR@10, NDCG@10 and MRR, statistical tests and a bias audit.
    HR@10 — user-based CF, best of five
    0.026
    better than random selection
    12.8×
    effect size behind p = 0.022
    d = 0.18
    • Python
    • NumPy
    • SciPy
    • scikit-learn
    • pandas
    • Matplotlib
    USER × ITEMRANKED TOP-100.195% DENSE · K-CORE FILTERED123456HR@10 · NDCG · MRRSchematic
  • 05Complete

    Data Science · Predictive Analytics · Business Intelligence

    Full-Cycle E-Commerce Churn & CLV

    An end-to-end churn and customer-value analysis of a Brazilian marketplace, from SQL engineering to an executive-ready retention plan.

    Problem
    Which customers are about to leave, how much revenue is at risk, and what should the marketing team do about it?
    Approach
    Built an analytical base table in SQL across nine relational tables, modeled churn with a temporal split, segmented customers with RFM, estimated CLV with BG/NBD and Gamma-Gamma, and turned the findings into five prioritized recommendations.
    customers
    96,096
    records across 9 tables
    1.55M
    actionable RFM segments
    8
    • Python
    • SQL
    • pandas
    • scikit-learn
    • XGBoost
    • LightGBM
    • Lifetimes
    • +1 more
    RFM SEGMENTSTEMPORAL SPLIT555155343211151432111R · F · M SCORESTRAINTESTSchematic

More engineering & data science work

Each one has its own write-up — select a project to read it.

02Experience

Where I've done the work.

About two years of hands-on work across LLM post-training and evaluation, independent AI product engineering, and data analysis.

  1. Aug 2025 – Present

    Independent product · Remote

    AI Engineer & Founder · IntelliCast AI

    Designing, building and operating a personalized agentic news product end to end.

    • Built the agent cycle: story clustering with pgvector, cross-outlet claim verification and goal-based ranking.
    • Streaming script → fact-check → voice pipeline with Llama 3.3 70B and Cartesia, in English and French.
    • Own the FastAPI backend, React frontend, Postgres data model, and AWS deployment with Docker, Terraform and CI.
    • LLM orchestration
    • Retrieval
    • Voice
    • Evaluation
    • AWS
  2. May 2024 – Jan 2026

    Contract · Remote

    AI Training Specialist · Outlier

    Contributed to LLM post-training and evaluation workflows.

    • Ranked model responses for RLHF preference data and wrote supervised fine-tuning examples.
    • Evaluated instruction following, reasoning and coding correctness against detailed rubrics.
    • Wrote adversarial prompts and tested for hallucinations and jailbreaks.
    • RLHF
    • SFT
    • LLM evaluation
    • Red-teaming
  3. Aug 2024 – Jan 2025

    Dallas, TX

    Data Analyst Intern · The African Think Tank

    Turned program and survey data into decisions for leadership.

    • Analyzed survey and program data with Python and SQL.
    • Built Tableau dashboards and decision-support reports.
    • Served as program manager for the organization's Kids Cultural Camp.
    • Python
    • SQL
    • Tableau
    • Reporting

03Skills

A toolkit organized by what it's for.

The tools I reach for across the lifecycle of an AI system — grouped by purpose, not ranked by percentage.

  • LLM & Agentic AI

    Orchestration, retrieval and evaluation for language-model systems.

    • LangGraph
    • LangChain
    • RAG
    • RAGAS
    • LLM Evaluation
    • Prompt Engineering
    • MCP
    • Hugging Face
  • Machine Learning

    Classical and deep learning, with models I can explain.

    • PyTorch
    • TensorFlow
    • scikit-learn
    • XGBoost
    • CatBoost
    • SHAP
    • Statistical Modeling
  • Backend & Data

    Typed services and the data layer underneath them.

    • Python
    • SQL
    • TypeScript
    • FastAPI
    • PostgreSQL
    • pgvector
    • ChromaDB
    • Redis
    • arq task queues
  • Infrastructure & MLOps

    Shipping, testing and watching what runs.

    • Docker
    • AWS EC2
    • GitHub Actions
    • CI/CD
    • Langfuse
    • Monitoring
    • Evaluation Pipelines
  • Analytics

    Questions answered with data, and communicated clearly.

    • pandas
    • NumPy
    • Tableau
    • Experimentation
    • Data Visualization
  • How I work

    • 01Evaluate before scaling
    • 02Measure, then claim
    • 03Degrade visibly, never silently
    • 04Verify against live systems

    Every case study documents what was measured, what broke, and what is still in progress.

04About

The engineering that makes AI useful beyond a demo.

I'm an AI engineer based in Dallas–Fort Worth with an M.S. in Data Science. My work spans agentic AI, retrieval systems, machine learning and LLM evaluation.

I've contributed to LLM post-training — ranking responses for RLHF, writing fine-tuning examples, and red-teaming for hallucinations and jailbreaks — and I build independent AI products and technical systems end to end, from data pipelines to deployment.

What I care about most is the unglamorous part: evaluation, data quality, reliability, deployment, latency and observable behavior. I write down what I measured, what broke and what I changed — and I label what isn't finished yet.

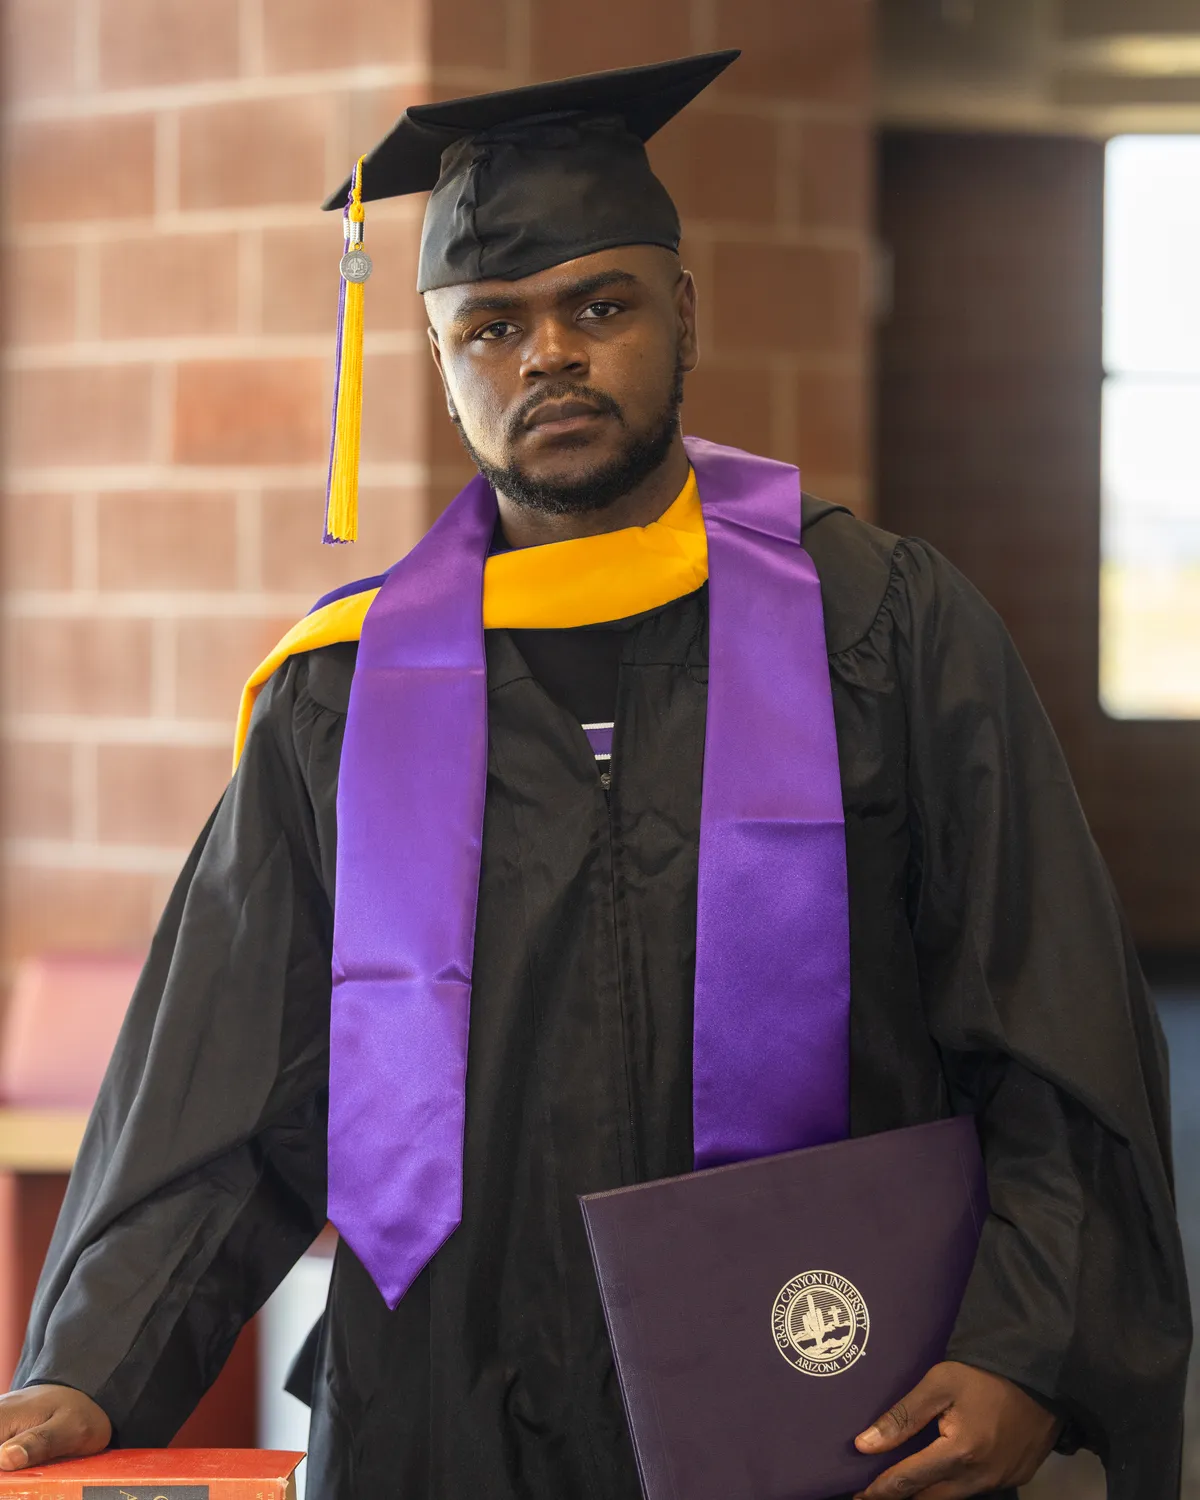
Armand Junior Dongmo Notue in graduation cap and gown, holding his Grand Canyon University diploma
M.S. Data Science, Grand Canyon University — 2025

05  —  Contact

Let's build something intelligent.

I'm open to opportunities where I can contribute to LLM applications, agentic AI, machine learning systems, and applied AI engineering.

Roles I'm targeting: GenAI Engineer · LLM Engineer · ML Engineer · AI Engineer · Data Scientist

Dallas–Fort Worth, TX · Remote-friendly · U.S. Permanent Resident — no visa sponsorship required